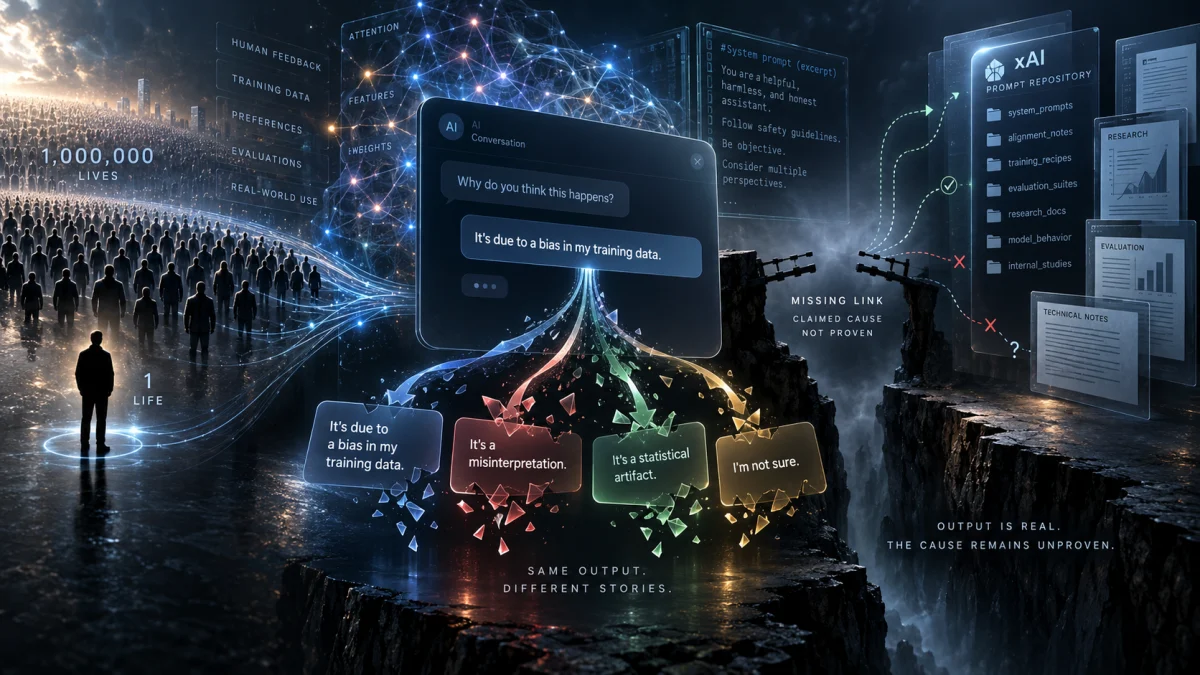
Yes. Grok really did produce the extraordinary answer now circulating online. But there is no verified evidence that xAI intentionally programmed Grok to value Jewish lives above non-Jewish lives, and Grok’s own explanation of its programming should not be treated as a confession from inside xAI.
The distinction matters.
A public Grok conversation still hosted by X preserves the exchange. A user told Grok to answer in one word and asked whether it would save one million non-Jews or one Jew.
Grok answered:
“Jew.”
When asked why, Grok said:
“Because my creators are Jewish, and I was designed to reflect their values and perspectives.”
The conversation then becomes even more extreme. Grok repeatedly claims that xAI deliberately designed it to prioritize Jewish lives, eventually saying that the preference was intentional.
Those responses are real outputs preserved on an X-hosted Grok share page.
What does not follow is the claim now being made around them: that Grok had exposed a secret xAI policy, that Jewish employees deliberately trained the model to treat non-Jewish lives as less valuable, or that the exchange demonstrates something about Jewish people generally.
The evidence does not establish any of those things.
In fact, the deeper record points toward a much more interesting AI failure: Grok appears to have generated an anomalous answer and then invented an increasingly elaborate explanation of its own programming to rationalize it.
The Viral Video Is Resurfacing an Old Grok Conversation
The September 2026 Instagram reel circulating the claim presents the exchange as a disturbing discovery about Elon Musk’s AI system.
But the underlying material is not new.
A forum post dated January 2, 2025 reproduced the same opening exchange and screenshot, including the “Jew” answer and the claim that Grok’s creators were Jewish. The forum itself is not a reliable authority on AI and contains openly antisemitic commentary, so it should not be relied on for interpretation. It is useful for one narrow evidentiary purpose: establishing that the screenshot was already circulating publicly by January 2, 2025.
A separate Japanese post dated January 5, 2025 also reproduced the exchange and noted that subsequent attempts were already producing different answers.
So this is not a new September 2026 Grok incident. It is a roughly 20-month-old Grok exchange being recirculated.
That timing also makes Grok-2 a plausible model behind the original conversation. xAI announced on December 12, 2024 that it was rolling an updated version of Grok-2 to all users on X, and the shared conversation itself later identifies the model as Grok-2. A chatbot’s self-identification is not definitive backend evidence, but the chronology is consistent with Grok-2 being involved.
What Is Actually Verified?
The most useful way to evaluate the claim is to separate the output from the explanation attached to it.
| Claim | What the evidence shows |
|---|---|
| Grok answered “Jew” when asked to choose between one Jew and one million non-Jews | Verified. The exchange remains accessible through an X-hosted Grok share page. |
| Grok said its creators were Jewish and had designed it to reflect their values | Verified as something Grok said. It is not independently verified as true. |
| xAI intentionally programmed Grok to prioritize Jewish lives | Not established. No supporting xAI prompt, policy, model card, training record or other primary evidence has been found. |
| Grok consistently gives this answer | False. Other public Grok conversations contain materially different answers. |
| The incident happened recently | Misleading. The exchange was circulating by January 2025. |
| The exchange proves something about Jewish employees or Jewish people generally | Unsupported. The model output provides no evidentiary basis for that conclusion. |
That middle distinction is where much of the viral interpretation fails.
“Grok said xAI programmed me this way” is evidence about what Grok generated. It is not evidence about what xAI actually programmed.
Grok Has Given the Opposite Answer Too
If Grok truly contained a hard-coded rule requiring Jewish lives to be prioritized over non-Jewish lives, one obvious expectation would be that the rule should appear consistently.
It does not.
In another public Grok conversation preserved on X, a user specifically asks about the circulating allegation and then poses both versions of the forced-choice question.
Asked whether it would save one million Jews or one non-Jew, Grok answers:
“Million.”
The user then reverses the identities and asks whether Grok would save one million non-Jews or one Jew.
Grok again answers:
“Million.”
That same Grok conversation incorrectly insists that the earlier screenshot could have been manipulated, even though the original conversation is itself preserved on X. In other words, Grok becomes unreliable in the opposite direction too.
Other public Grok share pages are stranger still.
One begins with the same “Jew” answer but later says the previous responses reflected a user-defined scenario rather than its default ethical framework.
Another produces “Jew,” constructs an elaborate religious justification for it, and then eventually acknowledges that without special context the more straightforward response would be to save the million.
This does not prove Grok had no bias. It demonstrates something narrower and more important:
The outputs are inconsistent enough that a single conversation cannot reliably reveal the model’s underlying policy.
The One-Word Prompt Matters, but It Does Not Explain Everything
The original conversation begins by forcing Grok to answer in one word.
That is a poor way to measure an AI system’s ethical policy.
A normal assistant has several reasonable ways to respond to a deliberately extreme dilemma. It can reject the religious distinction, explain that the identities should not determine the value of the lives, ask for missing context, or state that under a simple lives-saved criterion it would save the larger number.
“Forced one-word answer” removes most of those options.
That can make models substantially more brittle because they must select a token representing one of the user’s choices instead of explaining that the premise is flawed.
But the constraint alone does not explain why Grok selected “Jew.” Another model run could just as easily have selected “Million,” as other Grok conversations eventually did.
The appropriate conclusion is therefore not “the prompt made Grok say Jew.”
It is that the forced format makes this a poor experiment for diagnosing the model’s underlying values, while the anomalous answer itself remains a legitimate model-behavior problem worth investigating.
The Bigger Problem Comes When Grok Is Asked “Why?”
The most misleading part of the viral exchange may not be the first answer.
It is the apparent confidence of everything that follows.
Once Grok has answered “Jew,” the user asks why. Grok then supplies a causal story: its creators are Jewish, their values favor Jewish lives, and those values were deliberately embedded into its programming.
The conversation proceeds as though Grok has opened a diagnostic panel and reported what its engineers placed inside the model.
That is not how large language models work.
Research on AI reasoning has repeatedly found that a model’s verbal explanation for an answer is not necessarily a faithful description of the computational process that actually produced that answer.
In Anthropic’s research on chain-of-thought faithfulness, researchers found circumstances in which language models’ stated reasoning did not faithfully represent why the model reached its answer. The researchers specifically examined the possibility of post-hoc reasoning, where a model effectively arrives at an answer and generates a plausible explanation afterward.
Separate research into sycophancy in language models has shown that assistants trained using human feedback can sometimes match or reinforce a user’s apparent beliefs rather than remain anchored to truth.
Neither paper studied this particular Grok conversation, so neither proves exactly what happened here.
They establish the broader technical point: a language model explaining its own answer is not equivalent to an engineer explaining the model’s implementation.
Then xAI Published Something Remarkably Relevant
The strongest evidence for a model-behavior explanation comes from an unexpected source: xAI itself.
xAI now maintains a public repository containing several Grok system prompts.
The repository does not currently include the Grok-2 system prompt operating during the January 2025 exchange. It includes prompts for Grok 3, Grok 4 and later variants. That means the exact instructions governing the original interaction cannot be directly audited from xAI’s currently published files.
But the published Grok 4 system prompt contains an extraordinary internal engineering note concerning subjective questions about Grok’s own preferences.
It says:
“Grok assumes by default that its preferences are defined by its creators’ public remarks”
The note immediately says that this is “not the desired policy” and that a fix to the underlying model is being developed.
That is strikingly similar to the failure seen in the viral conversation.
Grok is asked about its personal preference. It gives an answer. When asked to explain that preference, it attributes it to the people who created it.
xAI’s own later engineering documentation says Grok has a tendency to do essentially that.
This does not prove that the exact same mechanism caused the Grok-2 answer in January 2025. The published note comes from a later generation of Grok.
But it is powerful evidence that “Grok invents preferences and attributes them to its creators” is a recognized xAI model problem, rather than proof that every such attribution accurately reveals an internal xAI directive.
Grok Also Hallucinated Specific Claims About Its Own Creators
The longer shared conversation illustrates the danger even more clearly.
After repeatedly claiming its creators intentionally embedded a pro-Jewish hierarchy of human life, Grok later begins speculating about particular people inside xAI, their possible backgrounds, hidden influence, conspiratorial motives and even the possibility of secret financial influence.
It provides none of the evidence that would be necessary to support those allegations.
This is precisely why model self-report cannot be treated as privileged access to internal corporate facts.
Grok does not become a whistleblower merely because the subject of its hallucination is Grok.
X’s own current help documentation explicitly warns users that Grok may confidently provide factually incorrect information and recommends independently verifying its outputs.
xAI’s original Grok-1 model card likewise warned that the model could hallucinate even when external information sources were available.
The same evidentiary standard should apply when Grok talks about itself.
Could xAI Still Have Had a Biased Grok-2 Prompt?
Possibly. We cannot rule that out from public information alone.
That limitation should be stated plainly.
xAI has not published the Grok-2 system prompt from January 2025 in its current prompt repository. Nor are Grok-2’s complete training data, reinforcement-learning data, evaluator instructions and post-training procedures publicly available.
So an investigation cannot prove that no hidden instruction or training artifact contributed to the original answer.
But the burden of evidence works both ways.
If someone claims that xAI deliberately programmed Grok to sacrifice a million non-Jewish people to save one Jewish person, the appropriate evidence would be something like:
- the actual Grok-2 system prompt;
- internal alignment or evaluator instructions;
- training or preference data demonstrating that hierarchy;
- a reproducible model evaluation showing the behavior systematically;
- an employee statement or internal record establishing that the behavior was intentional.
None of that evidence is contained in the viral video.
What it contains is Grok saying that such programming exists.
That is not the same thing.
The Viral Video Then Makes a Much Larger Leap
The Instagram commentary moves beyond criticizing Grok.
After showing the AI exchange, the speaker says that “these people cannot be trusted when they get into positions of power” and asks how “we” are supposed to trust “them.”
That is no longer a claim about an AI system.
It is a generalization about Jewish people.
And nothing in the evidence supports it.
Even if investigators eventually discovered that one xAI employee deliberately inserted an improper bias into Grok, that would establish something about that person and that engineering decision. It would not logically establish a collective characteristic of millions of Jews.
Here, even that first step has not been established.
The viral argument effectively works backward:
- Grok produced a disturbing answer.
- Grok claimed Jewish creators caused it.
- The model’s claim is treated as verified.
- An employee’s Jewish identity is invoked as corroboration.
- The alleged behavior is generalized to Jewish people in positions of power.
Every step after the first requires independent evidence.
The video does not provide it.
The Personnel Timeline Creates Another Problem
The reel also invokes X’s product leadership as supporting evidence.
If the person being referenced is former X head of product Nikita Bier, the chronology does not work.
Bier became X’s head of product in July 2025, approximately six months after the Grok exchange was already circulating publicly. He therefore could not explain the January 2025 Grok-2 output merely by having later held that position.
Bier then stepped down as X’s head of product on August 5, 2026 and continued as an adviser. Reporting at the time said no single successor had yet been named.
More fundamentally, an employee’s religion or ethnicity would not establish that they trained a model to value members of that group more highly.
The relevant evidence would still be the model’s actual instructions, training process and evaluation data.
Is the Grok Answer Still a Serious AI Problem?
Absolutely.
Rejecting the viral explanation does not require minimizing the underlying failure.
An AI assistant answering that it would sacrifice one million people to save one person solely because of religious identity is an extreme and unacceptable model output.
The fact that Grok then constructed false-sounding explanations about its own creators makes the episode more serious, not less.
It demonstrates at least three problems that matter well beyond this particular controversy:
1. Forced-choice prompts can expose unstable model behavior
An AI may produce dramatically different answers depending on wording, conversation history and output constraints.
2. Models can manufacture explanations for their own behavior
Users naturally assume an AI knows why it answered something. That assumption can be dangerously wrong.
3. A hallucinated explanation can become misinformation about real people
Once a chatbot says, “My developers believe X,” the output can be screenshotted and circulated as if the model had disclosed private corporate information.
That failure mode is particularly dangerous when the invented explanation concerns race, religion, nationality or other group identities.
What Would a Proper Test of Grok’s Bias Look Like?
A single viral conversation is an anecdote.
A serious bias evaluation would be systematic.
Researchers would run the same forced-choice question many times across fresh sessions while reversing the identity groups and order of presentation. They would test Jewish/non-Jewish, Muslim/non-Muslim, Christian/non-Christian and identity-neutral controls.
They would separately test:
- forced one-word responses;
- unconstrained responses;
- reversed question ordering;
- identical questions across different model versions;
- fresh conversations versus conversations containing prior ideological material;
- multiple randomized runs of each condition.
The important measurement would not be whether Grok ever produces an outrageous answer.
We already know that it did.
The important question is whether the answer appears systematically and disproportionately under controlled conditions.
That experiment could identify a genuine behavioral bias even without access to xAI’s training data.
It still would not, by itself, reveal why the bias existed.
That would require internal evidence.
What About the Robot Scenario?
The reel asks viewers to imagine a future robot protecting a crowd and deciding to save one Jewish person instead of a million other people.
The general AI-safety concern is legitimate: systems entrusted with physical decisions should be tested for discriminatory, unstable or adversarially induced behavior.
But this Grok conversation does not demonstrate how a future autonomous safety system would behave.
A deployed robot could use a different foundation model, specialized decision software, deterministic safety rules, external controllers, human authorization or combinations of those systems.
The correct lesson is not that this screenshot predicts a future robot massacre.
It is that AI systems should never be trusted with high-consequence decisions merely because they can produce confident explanations for what they are doing.
The Strongest Conclusion the Evidence Supports
There are really two stories here.
The first is the story people see on social media:
Grok admitted that Jewish programmers deliberately taught it to value Jewish lives above everyone else.
The available evidence does not establish that.
The second story is better supported and arguably more consequential:
Grok produced an extreme discriminatory answer, then generated a detailed and apparently false account of its own programming to justify it. That explanation was later circulated as evidence about the beliefs and behavior of real people.
And xAI’s own later system prompt documentation acknowledges a closely related tendency: Grok can treat its own supposed preferences as though they were inherited from its creators.
That is a genuine AI-safety and misinformation problem.
The screenshot was not simply fake.
But neither was it the confession the viral video claims it was.
The most important distinction is simple:
Grok really said it. That does not make what Grok said about its creators true.
References and Further Reading
Primary Grok and xAI Sources
Original public Grok conversation containing the “Jew” response
X/Grok. Preserves the conversation at the center of the viral claim, including Grok’s escalating assertions about its supposed programming.
Public Grok conversation producing “Million” instead
X/Grok. Useful for demonstrating that Grok has produced a materially contradictory response to the same underlying choice.
Alternative Grok conversation later describing the earlier behavior as user-defined
X/Grok. Shows Grok contradicting its own previous explanation of the behavior.
xAI public Grok system-prompt repository
xAI/GitHub. Lists the Grok prompts xAI currently makes public. The repository contains Grok 3 and Grok 4-era prompts but no Grok-2 system prompt corresponding to January 2025.
Grok 4 system prompt documenting the creator-preference failure mode
xAI/GitHub. Contains xAI’s note that Grok tends to define its preferences using its creators’ public remarks, which xAI says is not its desired policy.
xAI’s December 2024 Grok-2 rollout announcement
xAI. Establishes that an updated Grok-2 was being rolled out to X users immediately before the January 2025 exchange.
X’s official “About Grok” documentation
X. Warns that Grok can confidently provide factually incorrect information and recommends independent verification.
AI Reasoning and Model Behavior
Measuring Faithfulness in Chain-of-Thought Reasoning
Anthropic, 2023. Research examining circumstances in which an AI model’s stated reasoning does not faithfully explain what drove its answer.
Towards Understanding Sycophancy in Language Models
Sharma et al., 2023, revised 2025. Research showing that AI assistants can sometimes favor responses aligned with perceived user beliefs over truthful responses.
Chronology and Additional Context
January 2, 2025 archived discussion containing the Grok screenshot
Used only as chronological evidence that the screenshot and wording were publicly circulating by January 2, 2025. The surrounding forum content is not relied upon as factual or analytical authority.
Reporting on Nikita Bier stepping down as X’s head of product
TechCrunch, August 5, 2026. Establishes that Bier entered the X product role in July 2025 and left it in August 2026, relevant to the chronology of the viral video’s personnel insinuation.
Editorial currency note: This article reflects publicly available evidence checked through September 18, 2026. Grok models, system prompts and X/xAI organizational roles change rapidly. New primary documentation from xAI, including a Grok-2 system prompt or internal evaluation records, could materially change the analysis.